API
Uncompromising access to fundamental data
Standardized and ready for running research and training models with 500K+ tracked filers and billions of data points.
Programmatic access to the entire 3spread dataset
The same standardized fundamentals, ownership, and fund data behind the terminal, exposed as a clean REST API for your own systems. Point your code at one base URL and pull any filer, any period, and any filing family, without scraping EDGAR or wrangling raw XBRL yourself.
It is built for technical teams: predictable endpoints, typed responses, and a schema that stays the same as your coverage grows from one ticker to the whole market.
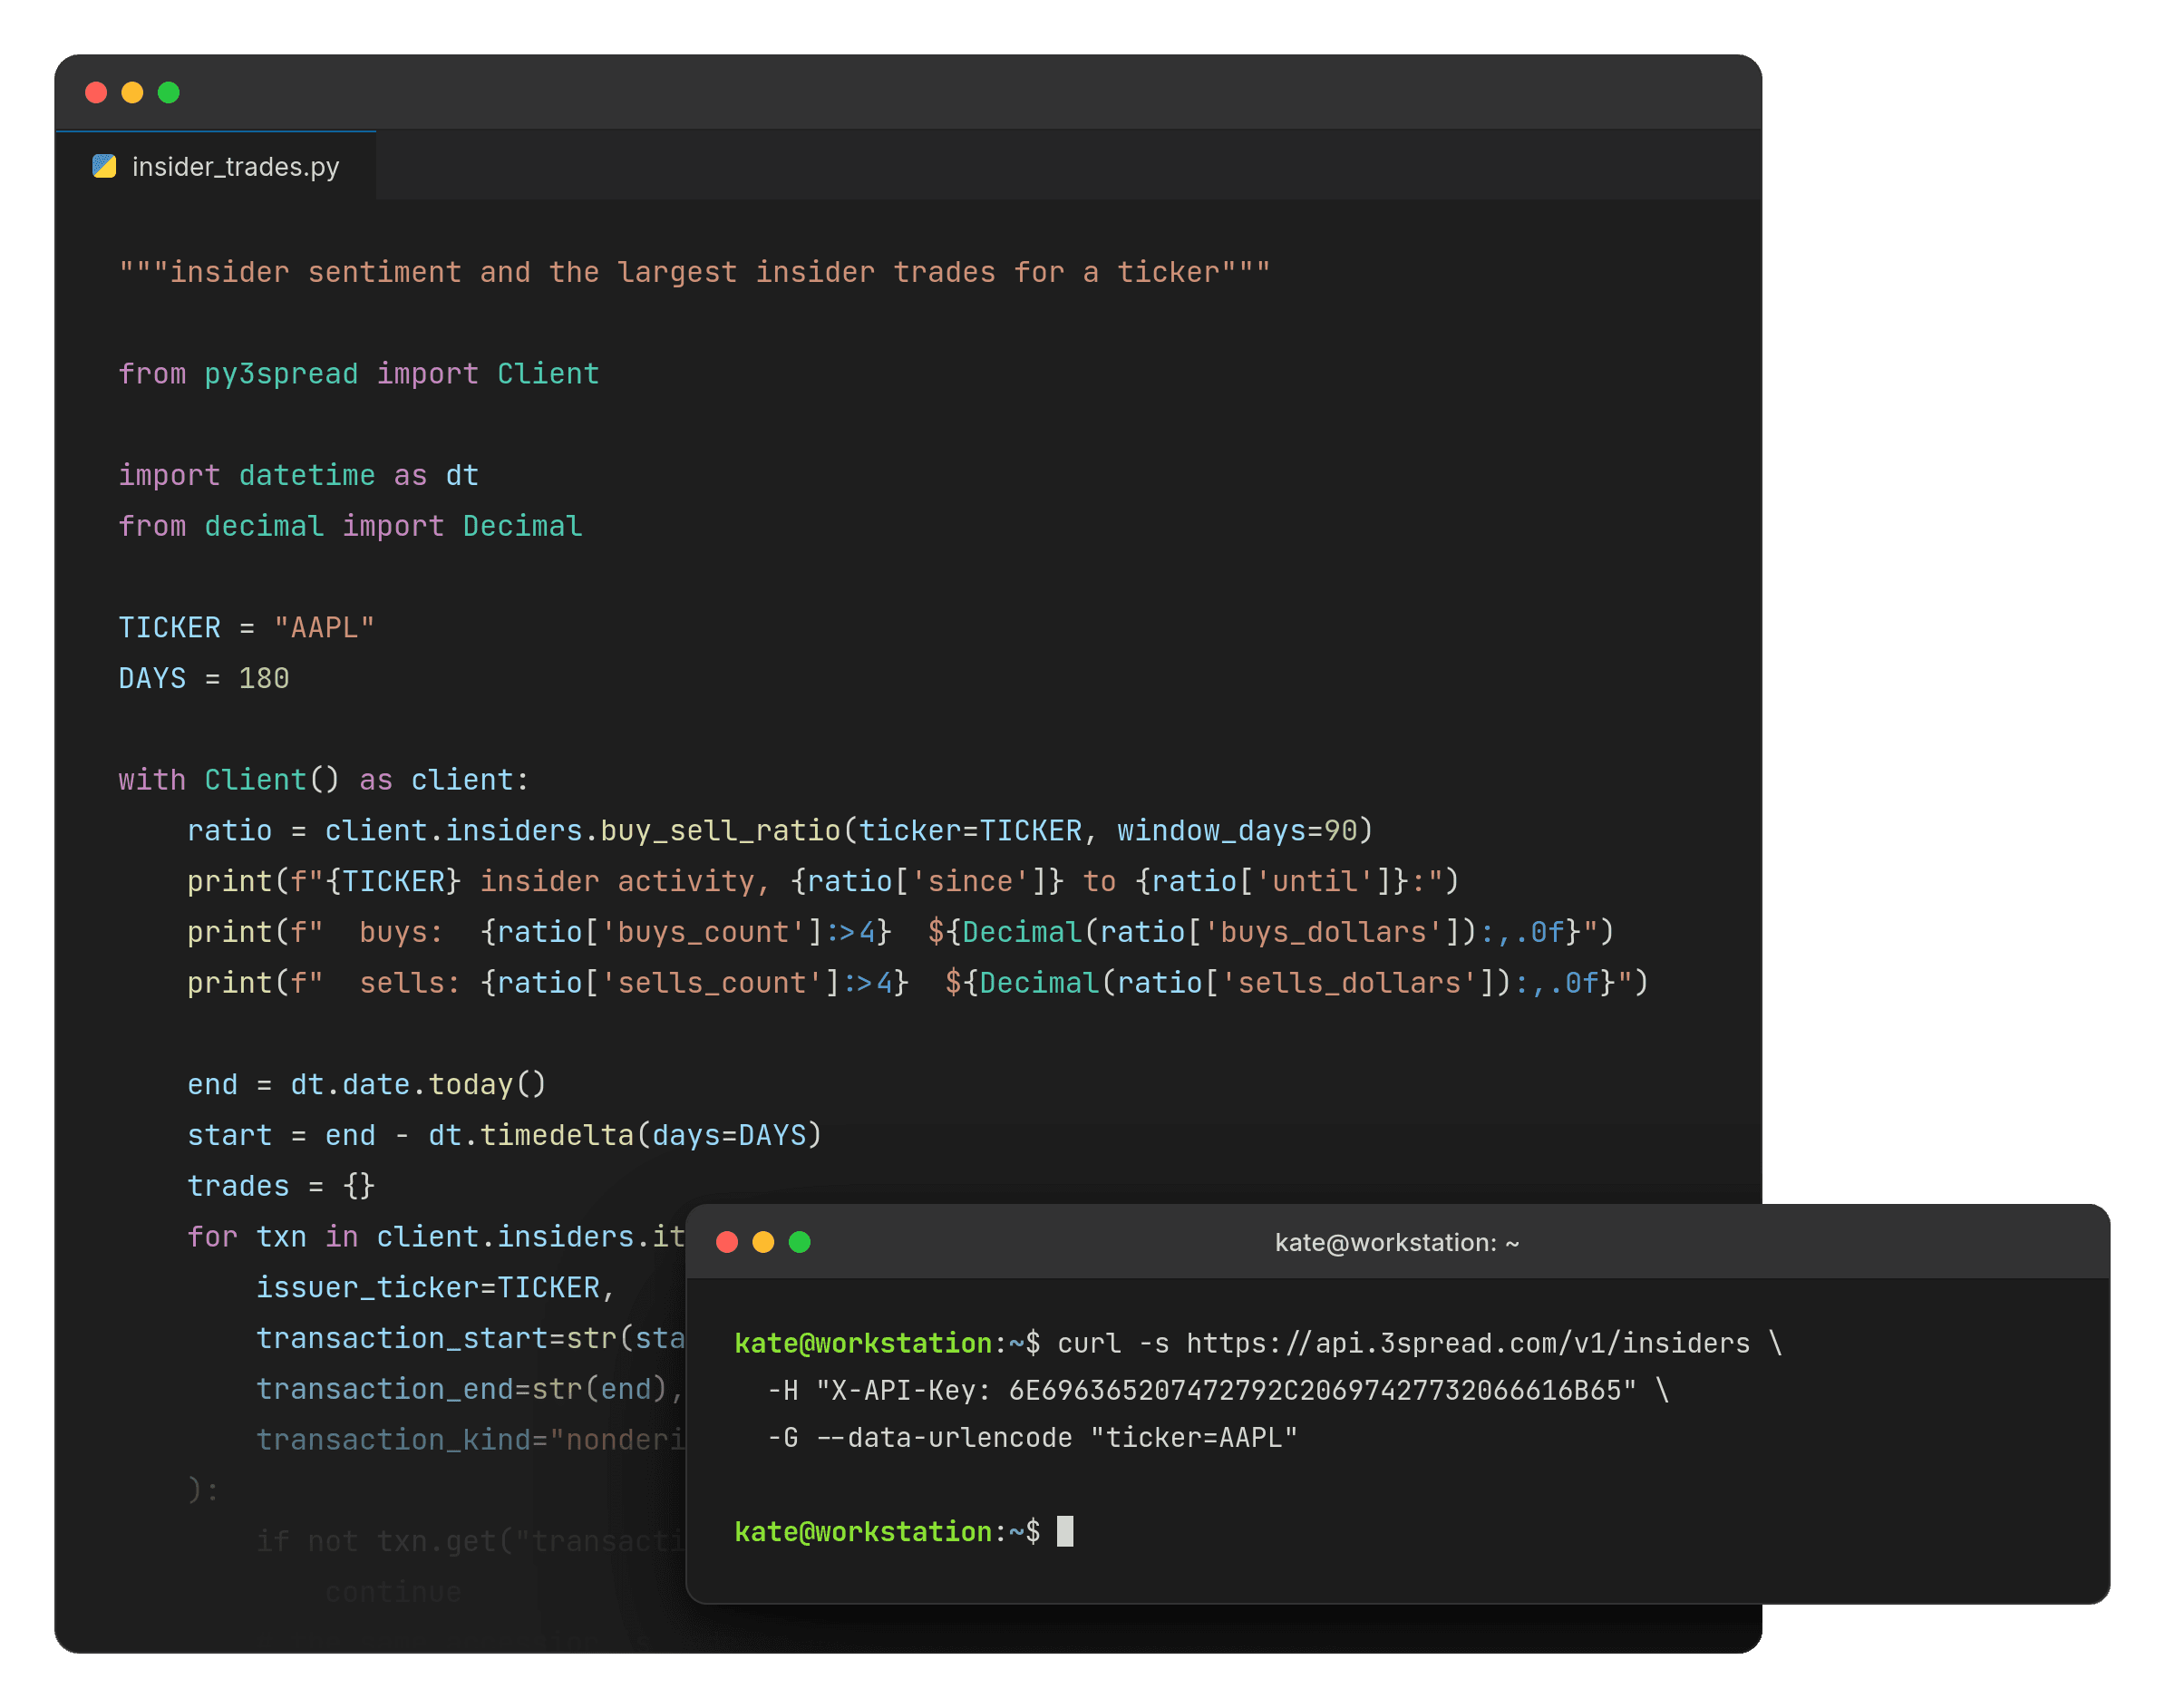
Designed to drop into your stack
There is nothing bespoke to learn before your first call. Everything speaks the conventions your tools already expect.
- Standard HTTP, JSON, and one sk_live_ key, plus an official Python SDK over the same /v1 endpoints
- One schema across every filer, so a query written once works everywhere
- Point in time and deterministic: as-reported figures stay separate from restatements, and the same filing returns the same output every run
- Verified: every statement reconciles to the filer's own reported totals before it is served
- Zero generative AI: only the filer's facts and our arithmetic, nothing paraphrased or inferred
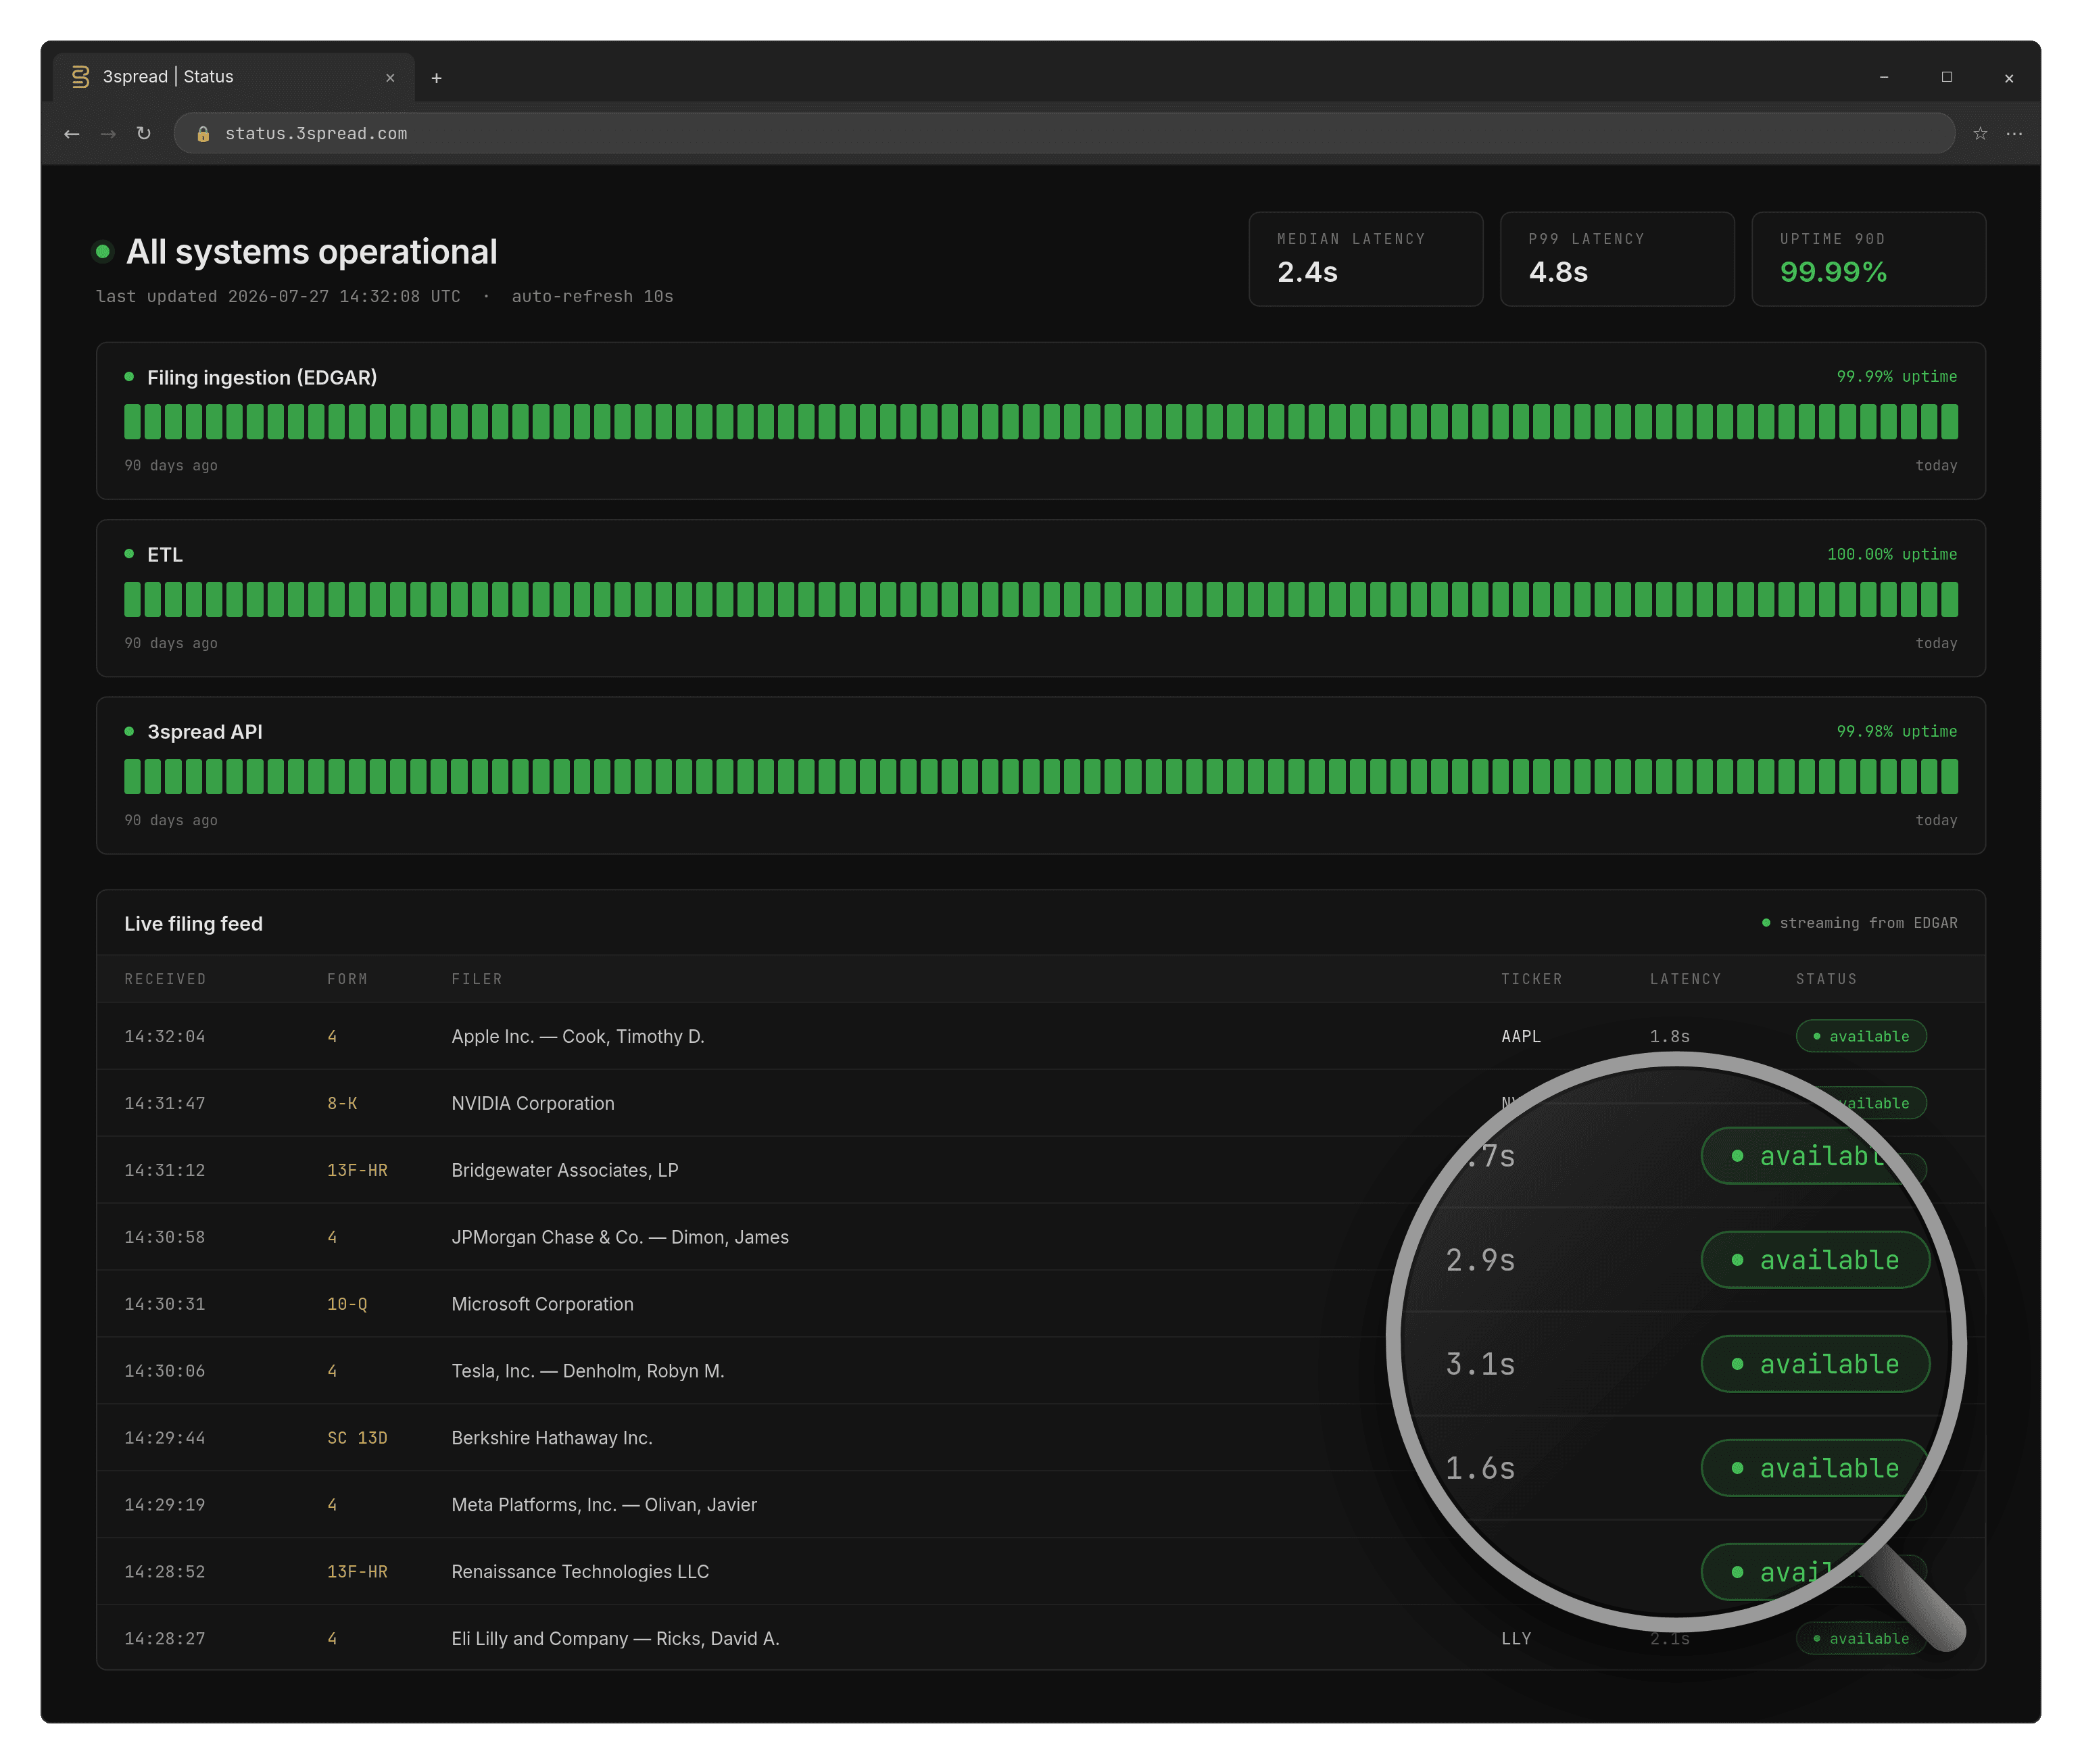
Live within seconds of the filing
As the SEC accepts a filing, it is parsed, standardized, and served within seconds. Your monitoring and your models act on it while it still moves the market, not after an overnight batch.
- A per-family changefeed streams created and amended events off a cursor, so incremental sync is one poll, not a full re-scan
- A freshness watermark reports the latest accepted time per family, so you can tell 'caught up' from 'stale' programmatically
- Amendments land as new, linked versions, so you see the change without losing the original
- The same pipeline serves live data and history going back to 2012
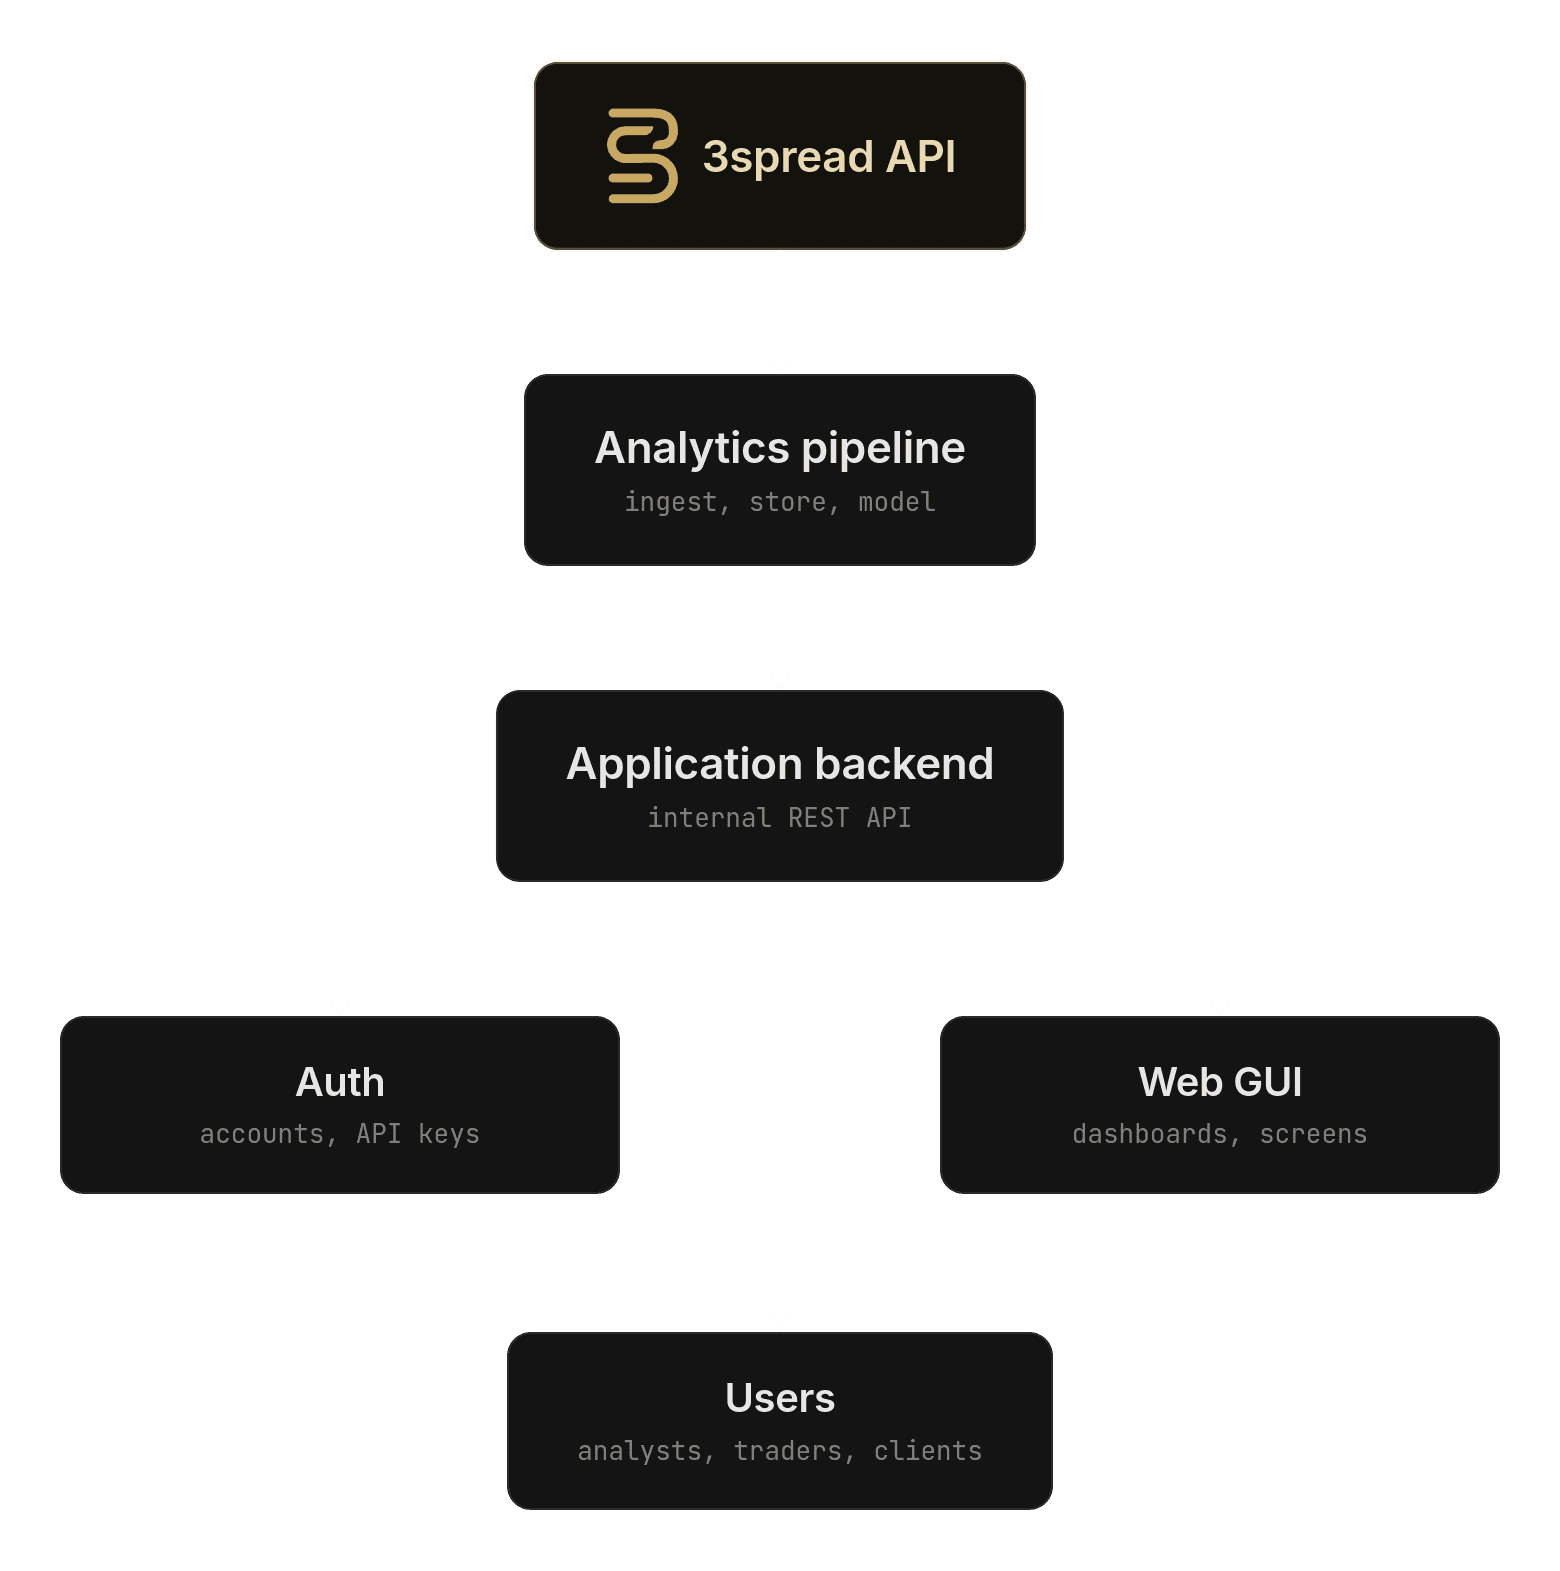
What teams build on it
Every dataset behind one API
46 endpoints across every filing family, all on the same authentication and the same response shape.
Start building
Where you go next depends on what you're after.